Saved searches
Use saved searches to filter your results more quickly
Cancel Create saved search
You signed in with another tab or window. Reload to refresh your session. You signed out in another tab or window. Reload to refresh your session. You switched accounts on another tab or window. Reload to refresh your session.
Have a question about this project? Sign up for a free GitHub account to open an issue and contact its maintainers and the community.
By clicking “Sign up for GitHub”, you agree to our terms of service and privacy statement. We’ll occasionally send you account related emails.
Already on GitHub? Sign in to your account
TRM crash with 2 cards; GPU detected DEAD will execute restart script watchdog.bat #292
DoruSonic opened this issue Apr 19, 2021 · 6 comments
TRM crash with 2 cards; GPU detected DEAD will execute restart script watchdog.bat #292
DoruSonic opened this issue Apr 19, 2021 · 6 comments
Comments
DoruSonic commented Apr 19, 2021
I have 2 cards. A 5700xt and a 570. I’ve had the 5700 for a few weeks and I got some stable settings, I then bought a 570 and its making the 5700 crash.
I’m using TRM and the 5700 is mining ETH while the 570 is mining RVN (with the corresponding -d parameter). They usually mine for a few hours together until the 5700 crashes with the «GPU detected DEAD will execute restart script watchdog.bat» error.
I’ve also found something weird is both can’t be mining unless I run the «windows_tdr_fix» again. If I start mining with the 570 and then start the 5700, the later crashes immediately. If I start the 5700 and then the 570, the 5700 also crashes immediately. The only way I managed to get both running is starting the 5700, launch the «windows_tdr_fix» and then the 570.
This would lead me to believe it’s the 570 fault, but its the 5700 that crashes so I’m not sure who is the culprit. I tried less aggressive OC on both cards to be on the safe side and still nothing.
I’m on Windows 10, both cards on risers, both with good thermals. PSU is 750W and they are using around 320W on the wall
The text was updated successfully, but these errors were encountered:
Bumblebee
Bumblebee is an effort to make NVIDIA Optimus enabled laptops work in GNU/Linux systems. Such feature involves two graphics cards with two different power consumption profiles plugged in a layered way sharing a single framebuffer.
Note: Bumblebee has significant performance issues[1][2]. See NVIDIA Optimus for alternative solutions.
Bumblebee: Optimus for Linux
Optimus Technology is a hybrid graphics implementation without a hardware multiplexer. The integrated GPU manages the display while the dedicated GPU manages the most demanding rendering and ships the work to the integrated GPU to be displayed. When the laptop is running on battery supply, the dedicated GPU is turned off to save power and prolong the battery life. It has also been tested successfully with desktop machines with Intel integrated graphics and an nVidia dedicated graphics card.
Bumblebee is a software implementation comprising two parts:
- Render programs off-screen on the dedicated video card and display it on the screen using the integrated video card. This bridge is provided by VirtualGL or primus (read further) and connects to a X server started for the discrete video card.
- Disable the dedicated video card when it is not in use (see the #Power management section)
It tries to mimic the Optimus technology behavior; using the dedicated GPU for rendering when needed and power it down when not in use. The present releases only support rendering on-demand, automatically starting a program with the discrete video card based on workload is not implemented.
Installation
Before installing Bumblebee, check your BIOS and activate Optimus (older laptops call it «switchable graphics») if possible (BIOS does not have to provide this option). If neither «Optimus» or «switchable» is in the BIOS, still make sure both GPUs will be enabled and that the integrated graphics (igfx) is initial display (primary display). The display should be connected to the onboard integrated graphics, not the discrete graphics card. If integrated graphics had previously been disabled and discrete graphics drivers installed, be sure to remove /etc/X11/xorg.conf or the conf file in /etc/X11/xorg.conf.d related to the discrete graphics card.
- bumblebee — The main package providing the daemon and client programs.
- mesa — An open-source implementation of the OpenGL specification.
- An appropriate version of the NVIDIA driver, see NVIDIA#Installation.
- Optionally install xf86-video-intel — Intel Xorg driver.
For 32-bit application support, enable the multilib repository and install:
- lib32-virtualgl — A render/display bridge for 32 bit applications.
- lib32-nvidia-utils or lib32-nvidia-340xx-utilsAUR (match the version of the regular NVIDIA driver).
In order to use Bumblebee, it is necessary to add your regular user to the bumblebee group:
# gpasswd -a user bumblebee
Also enable bumblebeed.service . Reboot your system and follow #Usage.
- The bumblebee package will install a kernel module blacklist file that prevents the nvidia-drm module from loading on boot. Remember to uninstall this if you later switch away to other solutions.
- The package does not blacklist the nvidiafb module. You probably do not have it installed, because the default kernels do not ship it. However, with other kernels you must explicitly blacklist it too, otherwise optirun and primusrun will not run. See FS#69018.
Usage
Test
Install mesa-utils and use glxgears to test if if Bumblebee works with your Optimus system:
$ optirun glxgears -info
If it fails, try the following commands (from virtualgl ):
$ optirun glxspheres64
If the window with animation shows up, Optimus with Bumblebee is working.
Note: If glxgears failed, but glxspheres64 worked, always replace glxgears with glxspheres64 in all cases.
General usage
$ optirun [options] application [application-parameters]
For example, start Windows applications with Optimus:
$ optirun wine application.exe
For another example, open NVIDIA Settings panel with Optimus:
$ optirun -b none nvidia-settings -c :8
Note: A patched version of nvdock AUR is available in the package nvdock-bumblebee AUR .
For a list of all available options, see optirun(1) .
Configuration
You can configure the behaviour of Bumblebee to fit your needs. Fine tuning like speed optimization, power management and other stuff can be configured in /etc/bumblebee/bumblebee.conf
Optimizing speed
One disadvantage of the offscreen rendering methods is performance. The following table gives a raw overview of a Lenovo ThinkPad T480 in an eGPU setup with NVIDIA GTX 1060 6GB and unigine-heaven AUR benchmark (1920×1080, max settings, 8x AA):
| Command | Display | FPS | Score | Min FPS | Max FPS |
|---|---|---|---|---|---|
| optirun unigine-heaven | internal | 20.7 | 521 | 6.9 | 26.6 |
| primusrun unigine-heaven | internal | 36.9 | 930 | 15.3 | 44.1 |
| unigine-heaven | internal in Nvidia-xrun | 51.3 | 1293 | 8.4 | 95.6 |
| unigine-heaven | external in Nvidia-xrun | 56.1 | 1414 | 8.4 | 111.9 |
Using VirtualGL as bridge
Bumblebee renders frames for your Optimus NVIDIA card in an invisible X Server with VirtualGL and transports them back to your visible X Server. Frames will be compressed before they are transported — this saves bandwidth and can be used for speed-up optimization of bumblebee:
To use another compression method for a single application:
$ optirun -c compress-method application
The method of compress will affect performance in the GPU/CPU usage. Compressed methods will mostly load the CPU. However, uncompressed methods will mostly load the GPU.
Here is a performance table tested with ASUS N550JV laptop and benchmark app unigine-heaven AUR :
| Command | FPS | Score | Min FPS | Max FPS |
|---|---|---|---|---|
| optirun unigine-heaven | 25.0 | 630 | 16.4 | 36.1 |
| optirun -c jpeg unigine-heaven | 24.2 | 610 | 9.5 | 36.8 |
| optirun -c rgb unigine-heaven | 25.1 | 632 | 16.6 | 35.5 |
| optirun -c yuv unigine-heaven | 24.9 | 626 | 16.5 | 35.8 |
| optirun -c proxy unigine-heaven | 25.0 | 629 | 16.0 | 36.1 |
| optirun -c xv unigine-heaven | 22.9 | 577 | 15.4 | 32.2 |
Note: Lag spikes occurred when jpeg compression method was used.
To use a standard compression for all applications, set the VGLTransport to compress-method in /etc/bumblebee/bumblebee.conf :
/etc/bumblebee/bumblebee.conf
[. ] [optirun] VGLTransport=proxy [. ]
You can also play with the way VirtualGL reads back the pixels from your graphic card. Setting VGL_READBACK environment variable to pbo should increase the performance. Compare the following:
PBO should be faster:
VGL_READBACK=pbo optirun glxgears
The default value is sync:
VGL_READBACK=sync optirun glxgears
Note: CPU frequency scaling will affect directly on render performance
Primusrun
Note: Since compositing hurts performance, invoking primus when a compositing WM is active is not recommended. See #Primus issues under compositing window managers.
primusrun (from primus ) is becoming the default choice, because it consumes less power and sometimes provides better performance than optirun / virtualgl . It may be run separately, but it does not accept options as optirun does. Setting primus as the bridge for optirun provides more flexibility.
For 32-bit applications support on 64-bit machines, install lib32-primus (multilib must be enabled).
You can either run it separately:
$ primusrun glxgears
Or as a bridge for optirun. The default configuration sets virtualgl as the bridge. Override that on the command line:
$ optirun -b primus glxgears
Alternatively, set Bridge=primus in /etc/bumblebee/bumblebee.conf and you will not have to specify it on the command line.
Tip: Refer to #Primusrun mouse delay (disable VSYNC) if you want to disable VSYNC . It can also remove mouse input delay lag and slightly increase the performance.
Pvkrun
pvkrun from the package primus_vk is a drop-in replacement for primusrun that enables to run Vulkan-based applications. A quick check can be done with vulkaninfo from vulkan-tools .
$ pvkrun vulkaninfo
Power management
This article or section is a candidate for merging with Hybrid graphics#Using bbswitch.
Notes: This section talks only about bbswitch which is not specific to Bumblebee. (Discuss in Talk:Bumblebee)
The goal of the power management feature is to turn off the NVIDIA card when it is not used by Bumblebee any more. If bbswitch (for linux ) or bbswitch-dkms (for linux-lts or custom kernels) is installed, it will be detected automatically when the Bumblebee daemon starts. No additional configuration is necessary. However, bbswitch is for Optimus laptops only and will not work on desktop computers. So, Bumblebee power management is not available for desktop computers, and there is no reason to install bbswitch on a desktop. (Nevertheless, the other features of Bumblebee do work on some desktop computers.)
To manually turn the card on or off using bbswitch, write into /proc/acpi/bbswitch:
# echo OFF > /proc/acpi/bbswitch # echo ON > /proc/acpi/bbswitch
Default power state of NVIDIA card using bbswitch
The default behavior of bbswitch is to leave the card power state unchanged. bumblebeed does disable the card when started, so the following is only necessary if you use bbswitch without bumblebeed.
Set load_state and unload_state module options according to your needs (see bbswitch documentation).
/etc/modprobe.d/bbswitch.conf
options bbswitch load_state=0 unload_state=1
To run bbswitch without bumblebeed on system startup, do not forget to add bbswitch to /etc/modules-load.d , as explained in Kernel module#systemd.
Enable NVIDIA card during shutdown
On some laptops, the NVIDIA card may not correctly initialize during boot if the card was powered off when the system was last shutdown. Therefore the Bumblebee daemon will power on the GPU when stopping the daemon (e.g. on shutdown) due to the (default) setting TurnCardOffAtExit=false in /etc/bumblebee/bumblebee.conf . Note that this setting does not influence power state while the daemon is running, so if all optirun or primusrun programs have exited, the GPU will still be powered off.
When you stop the daemon manually, you might want to keep the card powered off while still powering it on on shutdown. To achieve the latter, add the following systemd service (if using bbswitch ):
/etc/systemd/system/nvidia-enable.service
[Unit] Description=Enable NVIDIA card DefaultDependencies=no [Service] Type=oneshot ExecStart=/bin/sh -c 'echo ON > /proc/acpi/bbswitch' [Install] WantedBy=shutdown.target
Then enable the nvidia-enable.service unit.
Enable NVIDIA card after waking from suspend
The bumblebee daemon may fail to activate the graphics card after suspending. A possible fix involves setting bbswitch as the default method for power management in /etc/bumblebee/bumblebee.conf :
/etc/bumblebee/bumblebee.conf
[driver-nvidia] PMMethod=bbswitch [driver-nouveau] PMMethod=bbswitch
Note: This fix seems to work only after rebooting the system. Restarting the bumblebee service is not enough.
If the above fix fails, try the following command:
# echo 1 > /sys/bus/pci/rescan
To rescan the PCI bus automatically after a suspend, create a script as described in Power management#Hooks in /usr/lib/systemd/system-sleep.
Multiple monitors
Outputs wired to the Intel chip
If the port (DisplayPort/HDMI/VGA) is wired to the Intel chip, you can set up multiple monitors with xorg.conf. Set them to use the Intel card, but Bumblebee can still use the NVIDIA card. One example configuration is below for two identical screens with 1080p resolution and using the HDMI out.
/etc/X11/xorg.conf
Section "Screen" Identifier "Screen0" Device "intelgpu0" Monitor "Monitor0" DefaultDepth 24 Option "TwinView" "0" SubSection "Display" Depth 24 Modes "1920x1080_60.00" EndSubSection EndSection Section "Screen" Identifier "Screen1" Device "intelgpu1" Monitor "Monitor1" DefaultDepth 24 Option "TwinView" "0" SubSection "Display" Depth 24 Modes "1920x1080_60.00" EndSubSection EndSection Section "Monitor" Identifier "Monitor0" Option "Enable" "true" EndSection Section "Monitor" Identifier "Monitor1" Option "Enable" "true" EndSection Section "Device" Identifier "intelgpu0" Driver "intel" Option "UseEvents" "true" Option "AccelMethod" "UXA" BusID "PCI:0:2:0" EndSection Section "Device" Identifier "intelgpu1" Driver "intel" Option "UseEvents" "true" Option "AccelMethod" "UXA" BusID "PCI:0:2:0" EndSection Section "Device" Identifier "nvidiagpu1" Driver "nvidia" BusID "PCI:0:1:0" EndSection
You need to probably change the BusID for both the Intel and the NVIDIA card.
$ lspci | grep VGA
00:02.0 VGA compatible controller: Intel Corporation 2nd Generation Core Processor Family Integrated Graphics Controller (rev 09)
The BusID is 0:2:0. Note that lspci outputs hexadecimal values, but Xorg expects decimal values.
Output wired to the NVIDIA chip
On some notebooks, the digital Video Output (HDMI or DisplayPort) is hardwired to the NVIDIA chip. If you want to use all the displays on such a system simultaneously, the easiest solution is to use intel-virtual-output, a tool provided in the xf86-video-intel driver set, as of v2.99. It will allow you to extend the existing X session onto other screens, leveraging virtual outputs to work with the discrete graphics card. Usage is as follows:
$ intel-virtual-output [OPTION]. [TARGET_DISPLAY].
-d source display -f keep in foreground (do not detach from console and daemonize) -b start bumblebee -a connect to all local displays (e.g. :1, :2, etc) -S disable use of a singleton and launch a fresh intel-virtual-output process -v all verbose output, implies -f -V specific verbose output, implies -f -h this help
If this command alone does not work, you can try running it with optirun to enable the discrete graphics and allow it to detect the outputs accordingly. This is known to be necessary on Lenovo’s Legion Y720.
$ optirun intel-virtual-output
If no target displays are parsed on the commandline, intel-virtual-output will attempt to connect to any local display. The detected displays will be manageable via any desktop display manager such as xrandr or KDE Display. The tool will also start bumblebee (which may be left as default install). See the Bumblebee wiki page for more information.
When run in a terminal, intel-virtual-output will daemonize itself unless the -f switch is used. Games can be run on the external screen by first exporting the display export DISPLAY=:8 , and then running the game with optirun game_bin , however, cursor and keyboard are not fully captured. Use export DISPLAY=:0 to revert back to standard operation.
If intel-virtual-output does not detect displays, or if a no VIRTUAL outputs on «:0» message is obtained, then create:
/etc/X11/xorg.conf.d/20-intel.conf
Section "Device" Identifier "intelgpu0" Driver "intel" EndSection
which does exist by default, and:
/etc/bumblebee/xorg.conf.nvidia
Section "ServerLayout" Identifier "Layout0" Option "AutoAddDevices" "true" Option "AutoAddGPU" "false" EndSection Section "Device" Identifier "DiscreteNvidia" Driver "nvidia" VendorName "NVIDIA Corporation" Option "ProbeAllGpus" "false" Option "NoLogo" "true" Option "UseEDID" "true" Option "AllowEmptyInitialConfiguration" # Option "UseDisplayDevice" "none" EndSection Section "Screen" Identifier "Screen0" Device "DiscreteNvidia" EndSection
See [3] for further configurations to try. If the laptop screen is stretched and the cursor is misplaced while the external monitor shows only the cursor, try killing any running compositing managers.
If you do not want to use intel-virtual-output, another option is to configure Bumblebee to leave the discrete GPU on and directly configure X to use both the screens, as it will be able to detect them.
As a last resort, you can run 2 X Servers. The first will be using the Intel driver for the notebook’s screen. The second will be started through optirun on the NVIDIA card, to show on the external display. Make sure to disable any display/session manager before manually starting your desktop environment with optirun. Then, you can log in the integrated-graphics powered one.
Disabling screen blanking
You can disable screen blanking when using intel-virtual-output with xset by setting the DISPLAY environment variable appropriately (see DPMS for more info):
$ DISPLAY=:8 xset -dpms s off
Multiple NVIDIA graphics cards or NVIDIA Optimus
If you have multiple NVIDIA graphics cards (eg. when using an eGPU with a laptop with another built in NVIDIA graphics card) or NVIDIA Optimus, you need to make a minor edit to /etc/bumblebee/xorg.conf.nvidia . If this change is not made the daemon may default to using the internal NVIDIA card.
First, determine the BusID of the external card:
$ lspci | grep -E "VGA|3D"
00:02.0 VGA compatible controller: Intel Corporation HD Graphics 530 (rev 06) 01:00.0 3D controller: NVIDIA Corporation GM107M [GeForce GTX 960M] (rev a2) 0b:00.0 VGA compatible controller: NVIDIA Corporation GP104 [GeForce GTX 1070] (rev a1)
In this case, the BusID is 0b:00.0 .
Now edit /etc/bumblebee/xorg.conf.nvidia and add the following line to Section «Device» :
/etc/bumblebee/xorg.conf.nvidia
Section "Device" . BusID "PCI:11:00:0" Option "AllowExternalGpus" "true" # If the GPU is external . EndSection
Note: Notice that the hex 0b became a base10 11 .
Troubleshooting
Note: Please report bugs at Bumblebee-Project’s GitHub tracker as described in its wiki.
[VGL] ERROR: Could not open display :8
There is a known problem with some wine applications that fork and kill the parent process without keeping track of it (for example the free to play online game «Runes of Magic»).
This is a known problem with VirtualGL. As of bumblebee 3.1, so long as you have it installed, you can use Primus as your render bridge:
$ optirun -b primus wine windows program.exe
If this does not work, an alternative walkaround for this problem is:
$ optirun bash $ optirun wine windows program.exe
If using NVIDIA drivers a fix for this problem is to edit /etc/bumblebee/xorg.conf.nvidia and change Option ConnectedMonitor to CRT-0 .
Xlib: extension «GLX» missing on display «:0.0»
If you tried to install the NVIDIA driver from NVIDIA website, this is not going to work.
-
Uninstall that driver in the similar way:
# ./NVIDIA-Linux-*.run --uninstall
# rm /etc/X11/xorg.conf
[ERROR]Cannot access secondary GPU: No devices detected
In some instances, running optirun will return:
[ERROR]Cannot access secondary GPU - error: [XORG] (EE) No devices detected. [ERROR]Aborting because fallback start is disabled.
In this case, you will need to move the file /etc/X11/xorg.conf.d/20-intel.conf to somewhere else, restart the bumblebeed daemon and it should work. If you do need to change some features for the Intel module, a workaround is to merge /etc/X11/xorg.conf.d/20-intel.conf to /etc/X11/xorg.conf .
It could be also necessary to comment the driver line in /etc/X11/xorg.conf.d/10-monitor.conf .
If you are using the nouveau driver you could try switching to the nvidia driver.
You might need to define the NVIDIA card somewhere (e.g. file /etc/bumblebee/xorg.conf.nvidia ), using the correct BusID according to lspci output:
Section "Device" Identifier "nvidiagpu1" Driver "nvidia" BusID "PCI:0:1:0" EndSection
Observe that the format of lspci output is in HEX, while in xorg it is in decimals. So if the output of lspci is, for example, 0a:00.0 the BusID should be PCI:10:0:0 .
NVIDIA(0): Failed to assign any connected display devices to X screen 0
If the console output is:
[ERROR]Cannot access secondary GPU - error: [XORG] (EE) NVIDIA(0): Failed to assign any connected display devices to X screen 0 [ERROR]Aborting because fallback start is disabled.
If the following line in /etc/bumblebee/xorg.conf.nvidia does not exist, you can add it to the «Device» section:
Option "ConnectedMonitor" "DFP"
If it does already exist, you can try changing it to:
Option "ConnectedMonitor" "CRT"
After that, restart the Bumblebee service to apply these changes.
Failed to initialize the NVIDIA GPU at PCI:1:0:0 (GPU fallen off the bus / RmInitAdapter failed!)
Add rcutree.rcu_idle_gp_delay=1 to the kernel parameters of the boot loader configuration (see also the original BBS post for a configuration example).
Failed to initialize the NVIDIA GPU at PCI:1:0:0 (Bumblebee daemon reported: error: [XORG] (EE) NVIDIA(GPU-0))
You might encounter an issue when after resume from sleep, primusrun or optirun command does not work anymore. there are two ways to fix this issue — reboot your system or execute the following command:
# echo 1 > /sys/bus/pci/rescan
And try to test if primusrun or optirun works.
If the above command did not help, try finding your NVIDIA card’s bus ID:
$ lspci | grep VGA
00:02.0 VGA compatible controller: Intel Corporation Core Processor Integrated Graphics Controller (rev 02) 01:00.0 VGA compatible controller: nVidia Corporation Device 0df4 (rev a1)
For example, above command showed 01:00.0 so we use following commands with this bus ID:
# echo 1 > /sys/bus/pci/devices/0000:01:00.0/remove # echo 1 > /sys/bus/pci/rescan
Could not load GPU driver
If the console output is:
[ERROR]Cannot access secondary GPU - error: Could not load GPU driver
and if you try to load the nvidia module:
# modprobe nvidia
modprobe: ERROR: could not insert 'nvidia': Exec format error
This could be because the nvidia driver is out of sync with the Linux kernel, for example if you installed the latest nvidia driver and have not updated the kernel in a while. A full system update , followed by a reboot into the updated kernel, might resolve the issue. If the problem persists you should try manually compiling the nvidia packages against your current kernel, for example with nvidia-dkms or by compiling nvidia from the ABS.
NOUVEAU(0): [drm] failed to set drm interface version
Consider switching to the official nvidia driver. As commented here, nouveau driver has some issues with some cards and bumblebee.
[ERROR]Cannot access secondary GPU — error: X did not start properly
Set the «AutoAddDevices» option to «true» in /etc/bumblebee/xorg.conf.nvidia (see here):
Section "ServerLayout" Identifier "Layout0" Option "AutoAddDevices" "true" Option "AutoAddGPU" "false" EndSection
/dev/dri/card0: failed to set DRM interface version 1.4: Permission denied
This could be worked around by appending following lines in /etc/bumblebee/xorg.conf.nvidia (see here):
Section "Screen" Identifier "Default Screen" Device "DiscreteNvidia" EndSection
ERROR: ld.so: object ‘libdlfaker.so’ from LD_PRELOAD cannot be preloaded: ignored
You probably want to start a 32-bit application with bumblebee on a 64-bit system. See the «For 32-bit. » section in #Installation. If the problem persists or if it is a 64-bit application, try using the primus bridge.
Fatal IO error 11 (Resource temporarily unavailable) on X server
Change KeepUnusedXServer in /etc/bumblebee/bumblebee.conf from false to true . Your program forks into background and bumblebee do not know anything about it.
Video tearing
Video tearing is a somewhat common problem on Bumblebee. To fix it, you need to enable vsync. It should be enabled by default on the Intel card, but verify that from Xorg logs. To check whether or not it is enabled for NVIDIA, make sure nvidia-settings is installed and run:
$ optirun nvidia-settings -c :8
X Server XVideo Settings -> Sync to VBlank and OpenGL Settings -> Sync to VBlank should both be enabled. The Intel card has in general less tearing, so use it for video playback. Especially use VA-API for video decoding (e.g. mplayer-vaapi and with -vsync parameter).
Refer to Intel graphics#Tearing on how to fix tearing on the Intel card.
If it is still not fixed, try to disable compositing from your desktop environment. Try also disabling triple buffering.
Bumblebee cannot connect to socket
You might get something like:
$ optirun glxspheres64
$ optirun glxspheres32
[ 1648.179533] [ERROR]You have no permission to communicate with the Bumblebee daemon. Try adding yourself to the 'bumblebee' group [ 1648.179628] [ERROR]Could not connect to bumblebee daemon - is it running?
If you are already in the bumblebee group ( groups | grep bumblebee ), you may try removing the socket /var/run/bumblebeed.socket .
Another reason for this error could be that you have not actually turned on both GPUs in your BIOS, and as a result, the Bumblebee daemon is in fact not running. Check the BIOS settings carefully and be sure Intel graphics (integrated graphics — may be abbreviated in BIOS as something like igfx) has been enabled or set to auto, and that it is the primary GPU. Your display should be connected to the onboard integrated graphics, not the discrete graphics card.
If you mistakenly had the display connected to the discrete graphics card and Intel graphics was disabled, you probably installed Bumblebee after first trying to run NVIDIA alone. In this case, be sure to remove the /etc/X11/xorg.conf or /etc/X11/xorg.conf.d/20-nvidia.conf configuration files. If Xorg is instructed to use NVIDIA in a configuration file, X will fail.
Running X.org from console after login (rootless X.org)
Using Primus causes a segmentation fault
In some instances, using primusrun instead of optirun will result in a segfault. This is caused by an issue in code auto-detecting faster upload method, see FS#58933.
The workaround is skipping auto-detection by manually setting PRIMUS_UPLOAD environment variable to either 1 or 2, depending on which one is faster on your setup.
$ PRIMUS_UPLOAD=1 primusrun .
Primusrun mouse delay (disable VSYNC)
For primusrun , VSYNC is enabled by default and as a result, it could make mouse input delay lag or even slightly decrease performance. Test primusrun with VSYNC disabled:
$ vblank_mode=0 primusrun glxgears
If you are satisfied with the above setting, create an alias (e.g. alias primusrun=»vblank_mode=0 primusrun» ).
| VSYNC enabled | FPS | Score | Min FPS | Max FPS |
|---|---|---|---|---|
| FALSE | 31.5 | 793 | 22.3 | 54.8 |
| TRUE | 31.4 | 792 | 18.7 | 54.2 |
Tested with ASUS N550JV notebook and benchmark app unigine-heaven AUR .
Note: To disable vertical synchronization system-wide, see Intel graphics#Disable Vertical Synchronization (VSYNC).
Primus issues under compositing window managers
Since compositing hurts performance, invoking primus when a compositing WM is active is not recommended.[4] If you need to use primus with compositing and see flickering or bad performance, synchronizing primus’ display thread with the application’s rendering thread may help:
$ PRIMUS_SYNC=1 primusrun .
This makes primus display the previously rendered frame.
Problems with bumblebee after resuming from standby
In some systems, it can happens that the nvidia module is loaded after resuming from standby. One possible solution for this is to install the acpi_call and acpi package.
Optirun does not work, no debug output
Users are reporting that in some cases, even though Bumblebee was installed correctly, running
$ optirun glxgears -info
gives no output at all, and the glxgears window does not appear. Any programs that need 3d acceleration crashes:
$ optirun bash $ glxgears Segmentation fault (core dumped)
Apparently it is a bug of some versions of virtualgl. So a workaround is to install primus and lib32-primus and use it instead:
$ primusrun glxspheres64 $ optirun -b primus glxspheres64
By default primus locks the framerate to the vrate of your monitor (usually 60 fps), if needed it can be unlocked by passing the vblank_mode=0 environment variable.
$ vblank_mode=0 primusrun glxspheres64
Usually there is no need to display more frames han your monitor can handle, but you might want to for benchmarking or to have faster reactions in games (e.g., if a game need 3 frames to react to a mouse movement with vblank_mode=0 the reaction will be as quick as your system can handle, without it will always need 1/20 of second).
You might want to edit /etc/bumblebee/bumblebee.conf to use the primus render as default. If after an update you want to check if the bug has been fixed just use optirun -b virtualgl .
See this forum post for more information.
Broken power management with kernel 4.8
This article or section is a candidate for merging with Hybrid graphics#Using bbswitch.
Notes: Keep all info about bbswitch in one place. (Discuss in Talk:Bumblebee)
If you have a newer laptop (BIOS date 2015 or newer), then Linux 4.8 might break bbswitch (bbswitch issue 140) since bbswitch does not support the newer, recommended power management method. As a result, the GPU may fail to power on, fail to power off or worse.
As a workaround, add pcie_port_pm=off to your Kernel parameters.
Alternatively, if you are only interested in power saving (and perhaps use of external monitors), remove bbswitch and rely on Nouveau runtime power-management (which supports the new method).
Note: Some tools such as powertop —auto-tune automatically enable power management on PCI devices, which leads to the same problem [5]. Use the same workaround or do not use the all-in-one power management tools.
Lockup issue (lspci hangs)
See NVIDIA Optimus#Lockup issue (lspci hangs) for an issue that affects new laptops with a GTX 965M (or alike).
Discrete card always on and acpi warnings
Add acpi_osi=Linux to your Kernel parameters. See [6] and [7] for more information.
Screen 0 deleted because of no matching config section
Modify the configuration as follows:
/etc/bumblebee/xorg.conf.nvidia
. Section "ServerLayout" . Screen 0 "nvidia" . EndSection . Section "Screen" Identifier "nvidia" Device "DiscreteNvidia" EndSection .
Erratic, unpredictable behaviour
If Bumblebee starts/works in a random manner, check that you have set your Network configuration#Local network hostname resolution (details here).
Discrete card always on and nvidia driver cannot be unloaded
Make sure nvidia-persistenced.service is disabled and not currently active. It is intended to keep the nvidia driver running at all times [8], which prevents the card being turned off.
Discrete card is silently activated when EGL is requested by some application
If the discrete card is activated by some program (e.g. mpv with its GPU backend), it might stays on. The problem might be libglvnd which is loading the nvidia drivers and activating the card.
To disable this set environment variable __EGL_VENDOR_LIBRARY_FILENAMES (see documentation) to only load mesa configuration file:
__EGL_VENDOR_LIBRARY_FILENAMES="/usr/share/glvnd/egl_vendor.d/50_mesa.json"
nvidia-utils (and its branches) is installing the configuration file at /usr/share/glvnd/egl_vendor.d/10_nvidia.json which has priority and causes libglvnd to load the nvidia drivers and enable the card.
The other solution is to avoid installing the configuration file provided by nvidia-utils .
Framerate drops to 1 FPS after a fixed period of time
With the nvidia 440.36 driver, the DPMS setting is enabled by default resulting in a timeout after a fixed period of time (e.g. 10 minutes) which causes the frame rate to throttle down to 1 FPS. To work around this, add the following line to the «Device» section in /etc/bumblebee/xorg.conf.nvidia
Option "HardDPMS" "false"
Application cannot record screen
Using Bumblebee, applications cannot access the screen to identify and record it. This happens, for example, using obs-studio with NVENC activated. To solve this, disable the bridging mode with optirun -b none command .
See also
- Bumblebee project repository [dead link 2022-09-17 ⓘ]
- Bumblebee project wiki
- Bumblebee project bbswitch repository
TeamRedMiner: Команды и Параметры для майнинга
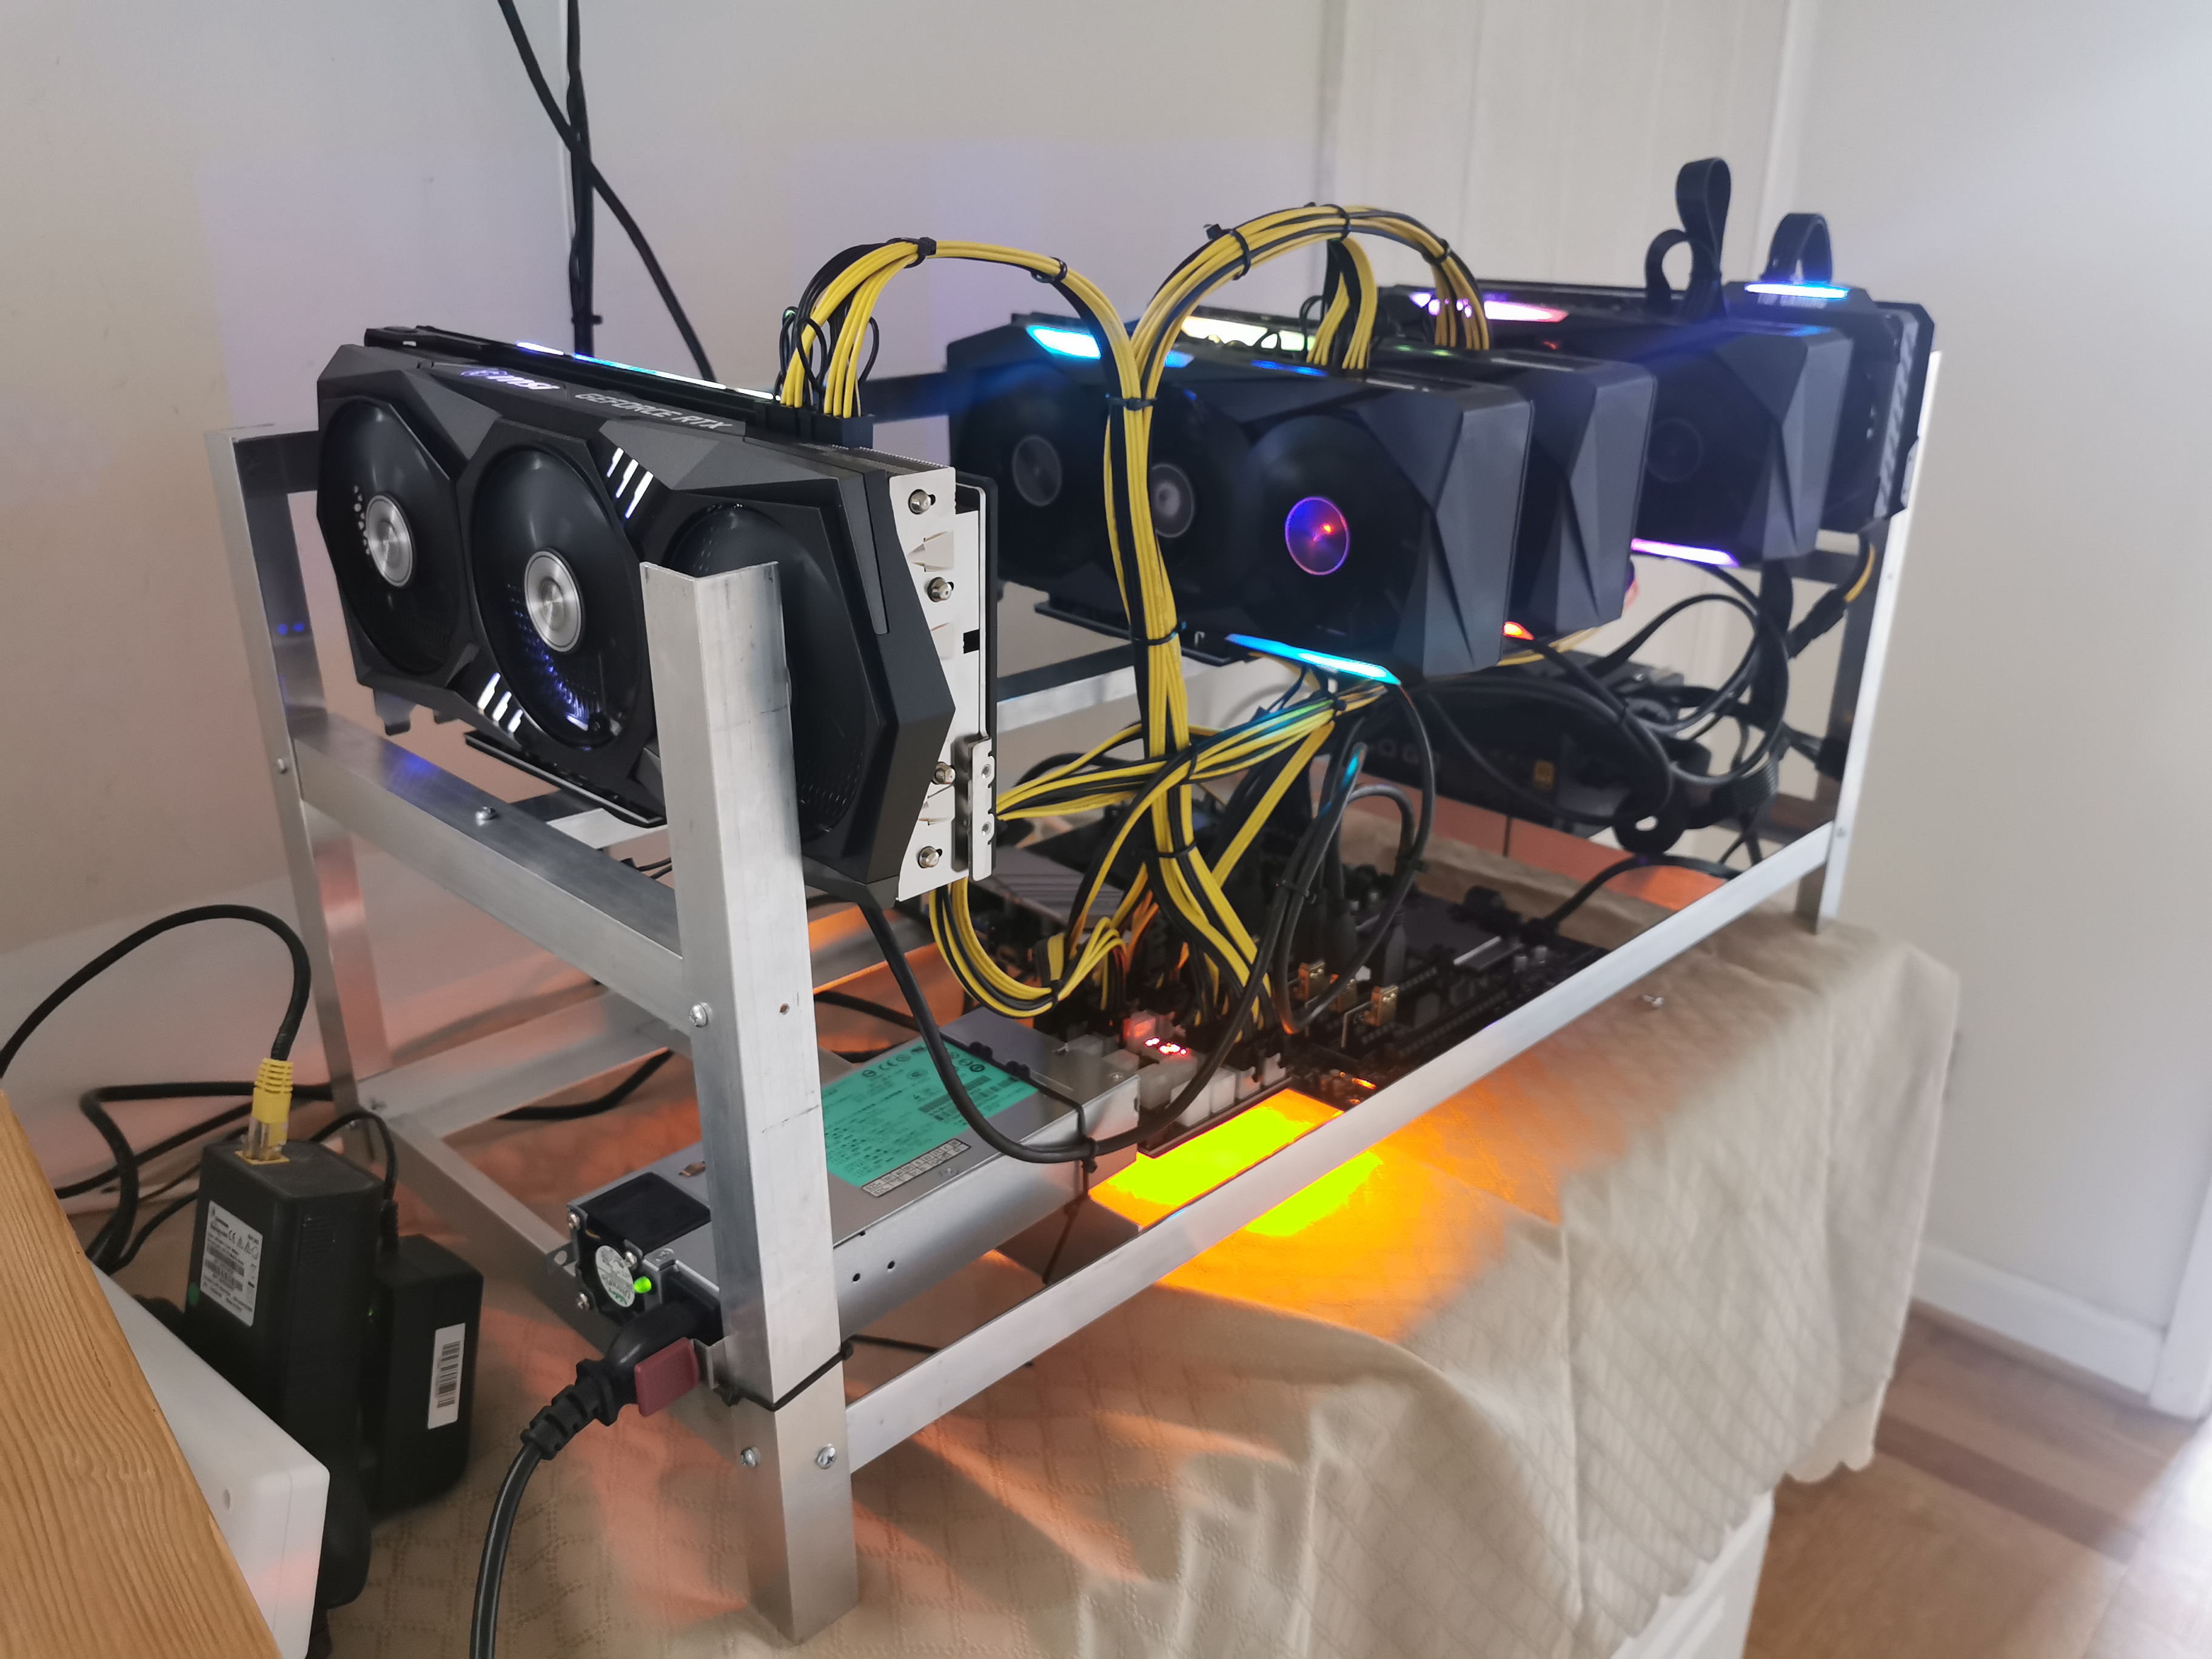
Аргументы командной строки — это аргументы, которые указываются после имени программы в системной командной строке, и значения этих аргументов передаются вашей программе во время выполнения.
Использование: teamredminer.exe -команда1 -команда2 -команда3
Пример для Ravencoin:
teamredminer.exe -a kawpow -o stratum+tcp://rvn.2miners.com:6060 -u RKAeArXkWLNERjWo5YF3R1xFnYCwKf11sX.worker_name -p x
Полный список параметров:
Алгоритм
—algo или краткий синоним этой команды -a — выбирает алгоритм майнинга.
Важно! Используйте либо длинный синоним, —algo= либо короткий -a . Вам не нужно использовать вместе два варианта одной и той же команды.
Дальнейшие команды будут разделены запятыми. Сначала короткий синоним, а затем длинный. Не забудьте использовать только один вариант.
Доступные на данный момент алгоритмы:
Алгоритм Криптовалюта ethash (eth, etp, others) etchash (etc, alias for -a ethash --eth_variant_mode=etchash) kawpow (ravencoin) firopow (firo) mtp_firopow (chooses firopow or mtp) autolykos2 (ergo) verthash (vtc) nimiq (nimiq) lyra2z phi2 (lux, argoneum) lyra2rev3 x16r x16rv2 x16s (pgn, xsh) x16rt (gin) mtp (zcoin/firo before the firopow fork) cuckatoo31_grin (grin) cuckarood29_grin (grin) cnv8 cnr (old monero) cnv8_half (stellite, masari) cnv8_dbl (x-cash) cnv8_rwz (graft) cnv8_trtl (old turtlecoin, loki) cnv8_upx2 (uplexa) cn_heavy (classic CN heavy) cn_haven (haven) cn_saber (bittube) cn_conceal (conceal) trtl_chukwa (turtlecoin) trtl_chukwa2 (turtlecoin) teamredminer.exe -a ethash
URL пула
-o — устанавливает URL пула и ПОРТ пула. В настоящее время поддерживаются протоколы stratum+tcp и stratum+ssl URL-адреса.
В этом примере URL-адрес ethash.poolbinance.com и порт 8888 . Значения должны быть разделены знаком :
Каждый раз, когда указывается эта опция, будет запускаться новая конфигурация пула.
Параметры для каждого пула (например -u , -p ) необходимо будет снова явно указывать для каждого нового пула. (См. пример файла start_multipool.sh/bat ).
Стратегия нескольких пулов для майнера устанавливается с —pool_strategy опцией.
SSL/TLS (для продвинутых пользователей)
Также имеется специальная поддержка расширенных настроек SSL/TLS, когда вам нужно передать имя хоста SNI конечной точке SSL. Например, это необходимо для конечных точек SSL, которые действуют как интерфейсы для нескольких хостов и должны знать, для какого из них предоставить сертификат. В таких случаях используйте следующий формат:
Это подключится к pool.tunnel.com:3333 , но передаст pool.realhostname.com в качестве имени хоста SNI на этапе подтверждения SSL. Разумеется, два имени хоста также могут быть идентичными.
Имя пользователя (логин пула) или адрес кошелька
-u , —user=USERNAME — устанавливает имя пользователя или адрес кошелька для авторизации майнинг-пула.
Если на пуле нет регистрации, то вместо логина нужно указать адрес кошелька.
Пароль (необязательно)
-p, —pass=PASSWORD — устанавливает пароль для авторизации пула.
Имя воркера (worker name)
Воркер — это название вашего виртуального “рабочего”. Это название указывается для простоты отслеживания статистики.
.worker — установите простое имя воркера для отслеживания вашего рига (фермы) в пуле. Имя работника указывается после знака wallet_address и перед ним ставится точка.
Минимальная настройка для запуска должна обеспечить только:
- адрес пула,
- адрес кошелька и
- имя воркера.
Просто скопируйте и измените адрес кошелька на адрес вашего кошелька. Это пример для Ethermine:
teamredminer.exe -a ethash -o stratum+tcp://eu1.ethermine.org:4444 -u 0x360d6f9efea21c82d341504366fd1c2eeea8fa9d.worker_name -p x
Список аргументов командной строки
-h , —help Display help message and exit.
—debug Enables debug log output.
—disable_colors Disables console output colors.
—force_colors Forces console color output even if the terminal does not seem to support them.
—api_listen=IP:PORT Enables the sgminer compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:4028 . For external access, use e.g. 0.0.0.0:4028 . It’s also valid to only specify the port, e.g. 4029 .
—cm_api_listen=IP:PORT Enables the claymore compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:3333 . For external access, use e.g. 0.0.0.0:3333 . It’s also valid to only specify the port, e.g. 3334 .
—cm_api_password=PSW Sets the required password for the CM compatible api interface.
Журнал (Logs)
—log_file(=FILENAME) Enables logging of miner output into the file specified by FILENAME . If no filename is provided, the miner will log to trm__ .log in the current working directory. If the log file already exists, the miner will append.
-l, —log_interval=SEC Set the time interval in seconds for averaging and printing GPU hashrates. SEC sets the interval in seconds, and must be > 0.
—log_rotate=SZ[,CNT] Enables log rotation. The SZ value sets the log size after which a new log file will be created. The SZ value supports the suffixes ‘k’, ‘M’, and ‘G’ and will multiply the value by 1024 , 1048576 , and 1073741824 respectively.
The optional CNT value sets the maximum number of old log files to keep. For example the option —log_rotate=4M,16 will cause the miner to switch to a new log file once the current log file exceeds 4194304 bytes in size, and the miner will keep the last 16 such files and delete older ones.
—short_stats Disables the full gpu state output in each hashrate output, like it was before 0.7.10.
—long_timestamps Enables microsec timestamps in the logs instead of seconds only.
—high_score Enables printouts of the top 15 shares found since miner start in the stats output.
—pool_debug Logs all pool traffic.
Комиссия (DevFee)
—dev_location=LOC Selects a specific location for the dev fee connection. Only use this if you see continuous dev fee connection issues reported by the miner. The connection management normally works well in all locations.
Available options are:
- world — Anywhere in the world except for mainland China.
- cn — Mainland China.
- non-gcp — Countries with blocked access to Google Services (e.g. Iran, Cuba).
Производительность
—enable_compute (Windows only) Enables compute mode and disables crossfire on necessary gpus.
—restart_gpus (Windows only) Restarts all configured gpus before mining, i.e. disable+enable PCI device.
—uac (Windows only) Enable privilege escalation when the miner runs tasks like restarting gpus.
You can always avoid this by running the miner directly as Administrator. This will trigger the standard Windows escalation prompt, so you have to be available to click ‘Yes’.
If this is not enabled, tasks that require Administrator privileges will fail when the miner is running under a basic user account.
Note: this might not be enabled for all algos.
—allow_dup_bus_ids Allows multiple gpus using the same pci bus id. This should only be used for Radeon Pro Duo cards and similar hardware, it’s normally an indication of a broken OpenCL environment.
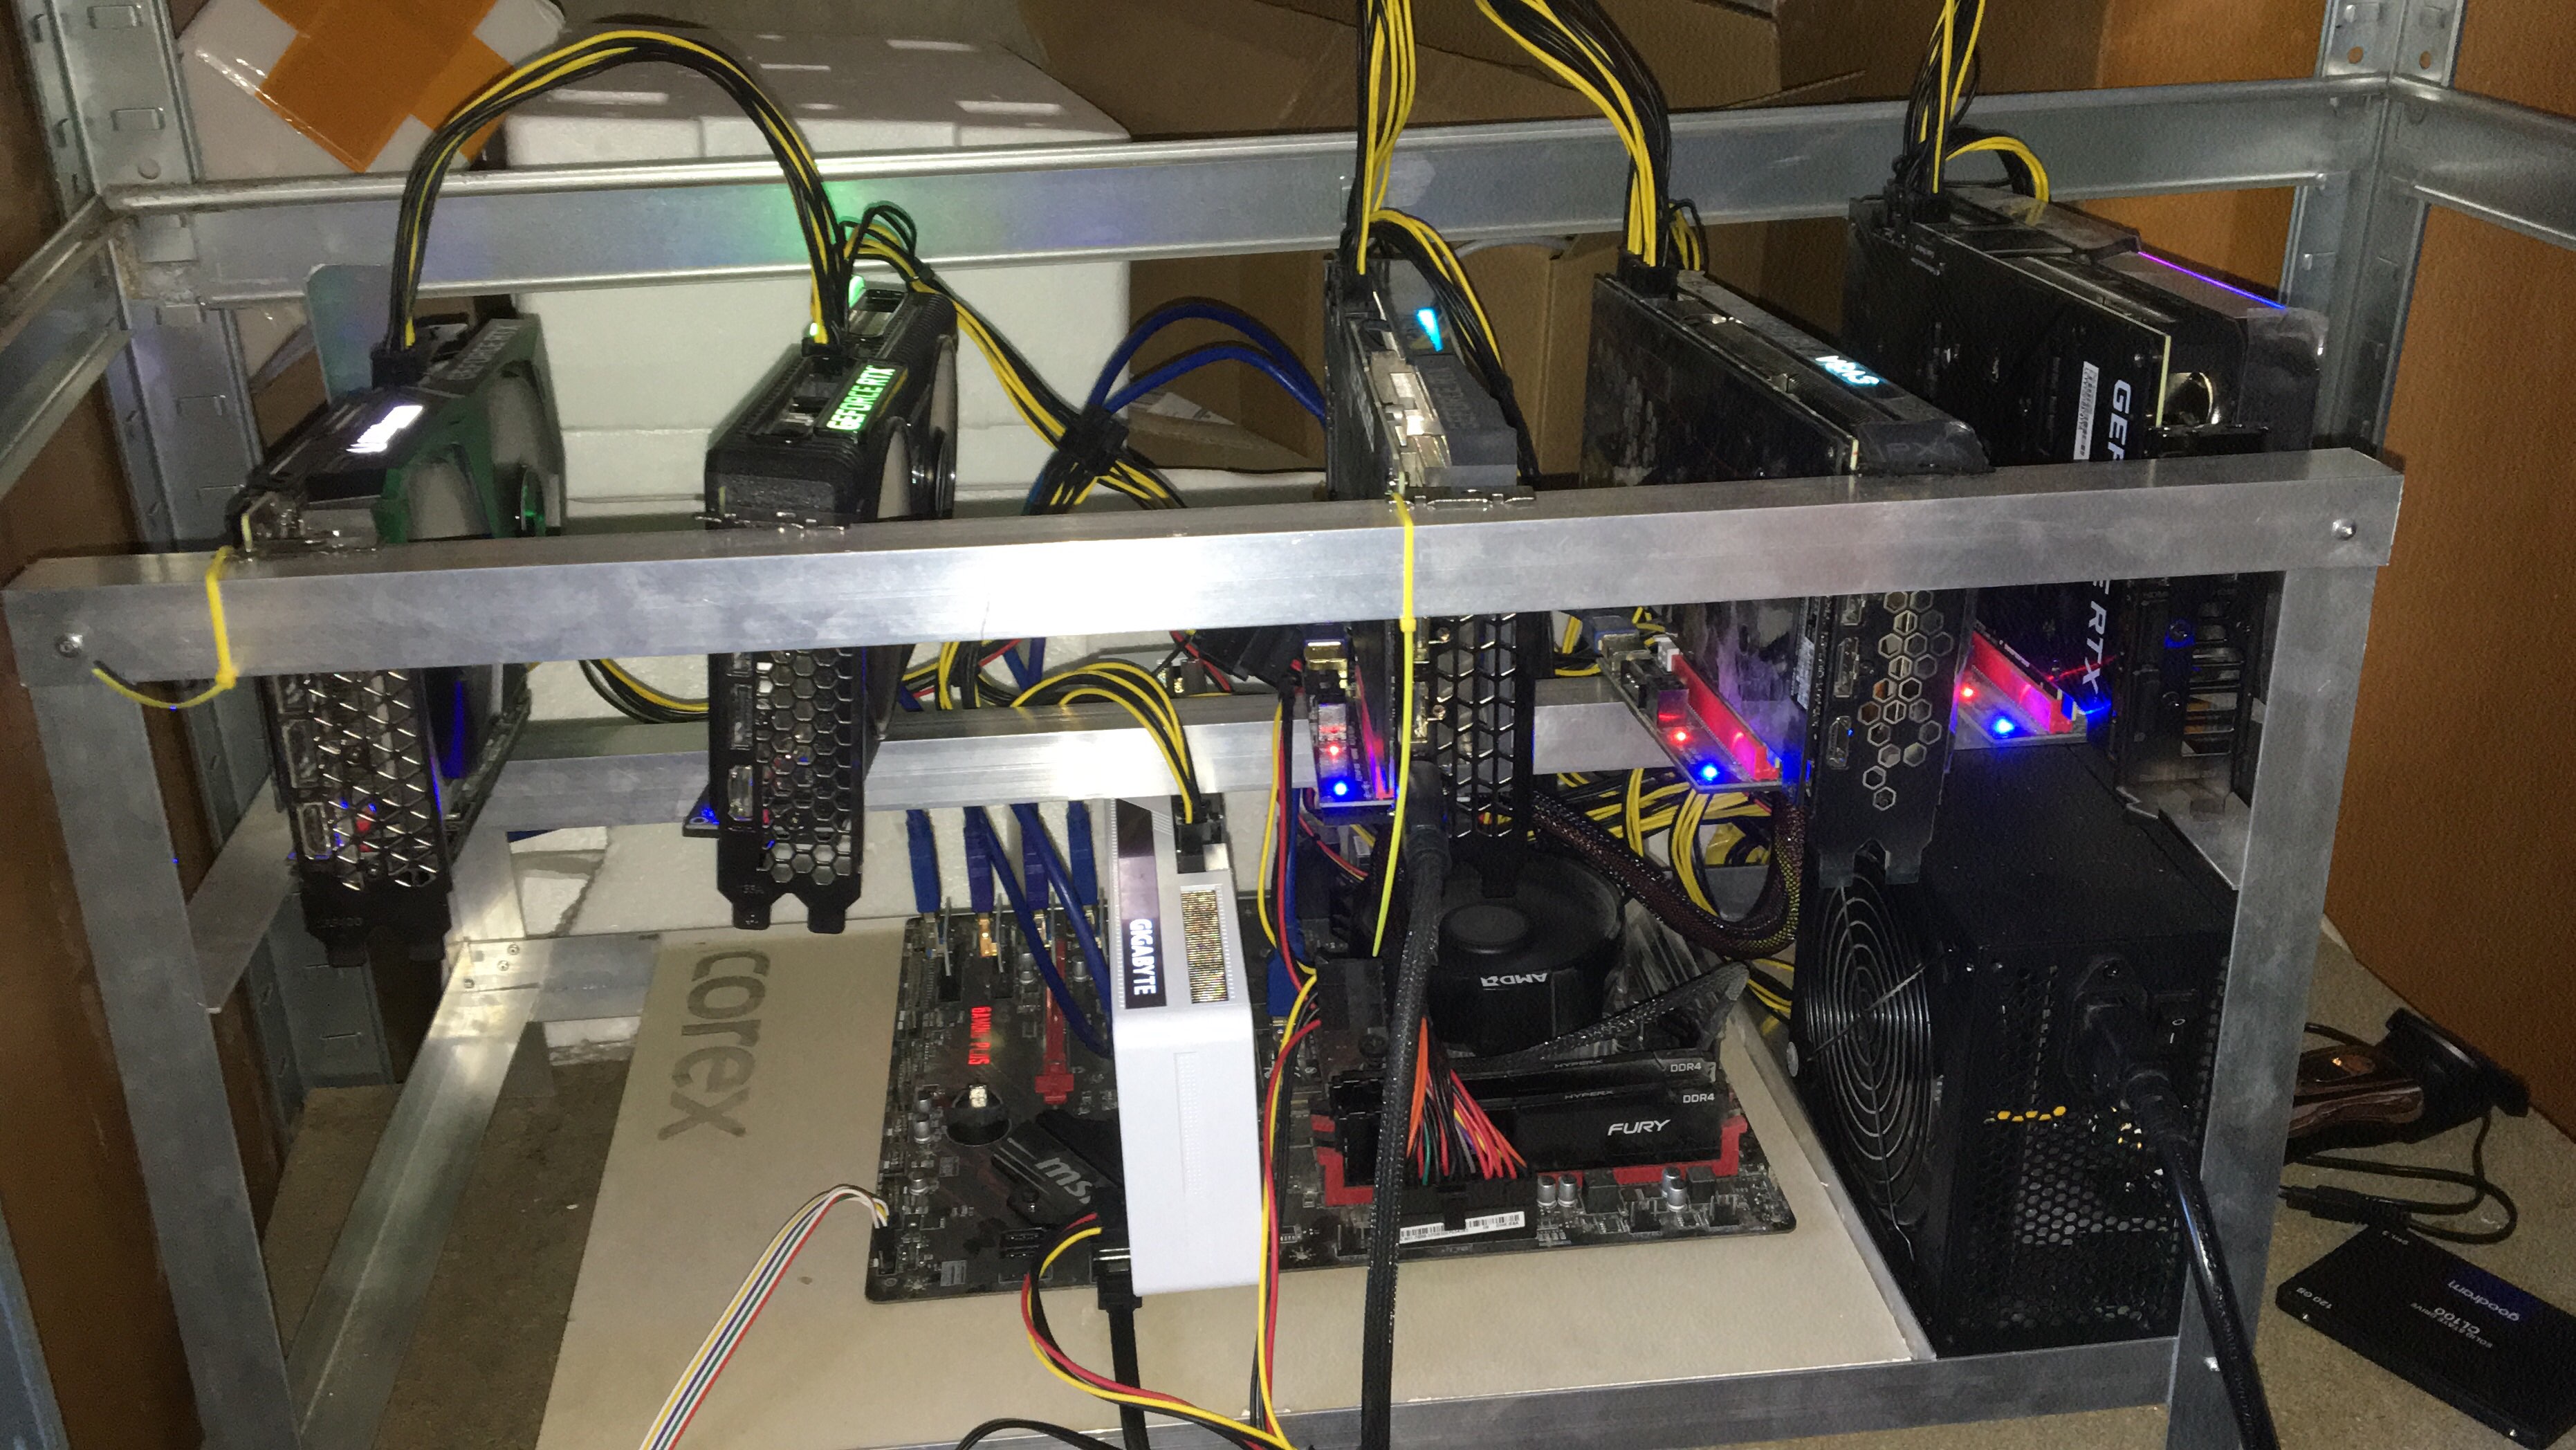
Подключение к пулу
-o, —url=URL Sets the pool URL. Currently stratum+tcp and stratum+ssl URLs are supported.
- Each additional time this option is specified will start a new pool config.
- Per-pool options (such as -u, -p) will need to be explicitly specified again for each new pool. (See the example start_multipool.sh/bat file)
- The multi-pool strategy for the miner is set with the –pool_strategy option.
There is also special support for advanced SSL/TLS setups where you need to pass a SNI hostname to the SSL endpoint. For example, this is necessary for SSL endpoints that act as frontends for multiple hosts and need to know which one to provide a certificate for. In such cases, use the following format:
This will connect to pool.tunnel.com:3333 but pass pool.realhostname.com as the SNI hostname in the SSL handshake phase. The two hostnames can of course be identical as well.
-u , —user=USERNAME Sets the username for pool authorization.
-p , —pass=PASSWORD Sets the password for pool authorization.
—pool_force_ensub Forces an extranonce subscribe request for supported pools unknown to the miner.
—pool_no_ensub Prevent miner from sending extranonce subscribe request to the pool.
—pool_broken_rpc Tells the miner to only allow a single outstanding rpc request on the pool connection. This is a work-around for pools that violate the json rpc specification regarding rpc IDs.
—pool_ratio=RATIO Sets the hashrate ratio between pools when using multiple pools with the the load_balance or quota pool strategies (see —pool_strategy ). By default all pools use the ratio value 1. For example, using this option with a value of 2 on just one pool will make that pool receive twice the hashrate as the other pools since their ratio will still be the default value of 1.
Глобальные опции пула
—pool_connect_TO=SEC Set the time-out for attempting to connect to a pool. SEC is the time to wait in seconds. Default is 10.
—pool_rpc_TO=SEC Set how long the miner will wait for an unanswered RPC to the pool. After this time, the miner will reconnect to the pool. SEC is the time to wait in seconds.
Default is 60.
—pool_max_rejects=N If a pool rejects N shares in a row, the pool connection is reset. This is to prevent against pools that invalidates mining sessions without disconnecting the user.
Default value is 5.
—pool_share_limit_ms=N If a pool takes longer than N ms to accept or reject a share, kill the current connection and reconnect. This is intended for pools that often get issues with some of their servers, but reconnecting means being load-balanced to a different and hopefully better server. Default value is no timeout.
—pool_strategy=STRAT Sets the strategy for selecting pools when running with multiple pools.
The available values are:
- priority,
- load_balance,
- quota, and
- min_epoch.
The default is priority.
- priority : The miner will use pools in the order they are listed, only moving on to the next pool if the previous cannot establish a connection.
- load_balance : The miner will evenly balance the hashrate across all currentlyconnected pools. The ratio of hashrate between pools can be set with —pool_ratio .
- quota : The miner will evenly balance the total hashes completed across all pools. If a pool disconnects and later reconnects, the miner will move hashrate to the pool until the total hashes for each pool is balanced.
The ratio of hashrate between pools can be set with —pool_ratio .
- min_epoch : ETH + ZIL switching strategy. The miner will always mine the lowest epoch among all connected pools, and in case of a tie, the first connected pool.
Therefore, specify your ETH mining pool as the first/primary pool, then the ZIL pool as the second pool. You can also use ‘eth_zil’ as the name for this strategy.
—no_ntime_roll Prevents the miner from rolling ntime in the block header, only using the value provided by the pool. This needs to be enabled for some pools when mining x16rt .
—no_stale_submit Prevents the miner from submitting shares that are not for the most current pool job.
Опция выбора видеокарт
—platform=INDEX Sets the index of the OpenCL platform to use. If not specified, platform will be auto-detected. Linux with multiple platforms is only supported using no —platform arg but instead adding —bus_reorder .
-d , —devices=DEVLIST Sets gpu devices to use from detected list. DEVLIST should be a comma-separated list of device indices, e.g. -d 0,1,2,4. If not specified, alldevices on the platform(s) will be used. NOTE: by default the devices are orderedby pcie bus ordering. Use —list_devices to show indices.
—init_style=1/2/3 Specified the init style (1 is default):
- One gpu at the time, complete all before mining.
- Three gpus at the time, complete all before mining.
- All gpus in parallel, start mining immediately.
—pcie_fmt=FORMAT Sets print format for pcie bus numbers. The accepted values for FORMAT are either hex or dec . The default is dec for windows and hex for linux.
—bus_reorder Reorders the detected or specified devices after their pcie bus id. If noplatform is specified, devices will be collected from all detected AMD OpenCLplatforms. Note: As of version v0.7.0 this is the default behavior.
—opencl_order Orders the detected or specified devices in the order OpenCL presents them.
—list_devices Lists the available devices for the detected or specified platform and exits immediately. Bus reordering will be implemented in the displayed order.
—nr_cu_override=X,Y. Overrides the nr compute units per gpu as presented by the OpenCL API. This is primarily useful for Vega 64s flashed with 56 biosed and where the driver is reporting 56 CU instead of the true count. Provide a comma-separated list of the override CU count per gpu as value for the argument.
You can skip gpus and do not need to provide values for all gpus in the rig. Example for a mixed rig of two Vegas at index 1 and 3 and two other gpus: –nr_cu_override=,64,,64. You can verify your argument by also adding —list_devices before mining.
Варианты управления разгоном / напряжением (только для Windows, BETA функциональность)
The miner has basic functionality for setting core and mem clks and their respective voltage, as well as selecting between the win driver’s built-in timings. For each available argument below, you enumerate values for gpu(s) in the rig in a comma-separated list.
Some arguments are not used for certain gpus. You can skip gpus in the list.
The miner always sets and uses the highest p-state for both core and mem for GCN gpus (Polaris, Vega). Please note that Rx Vega gpus must have a powerplay table modification of the mem p2 state before being able to run a voltage lower than 900mV. Moreover, Big Navi gpus also still need to use e.g. MorePowerTool to make powerplay table modifications, for example for enabling setting a lower voltage. The miner might add support for powerplay table-related functionality in the future.
—clk_debug Enable start-up log printouts related to setting clocks/voltages/timings.
—clk_core_mhz=MHZ1,MHZ2. Sets the core clk per gpu in MHz.
—clk_core_mv=MV1,MV2. Sets the core voltage per gpu in mV.
—clk_mem_mhz=MHZ1,MHZ2. Sets the mem clk per gpu in MHz.
—clk_mem_mv=MV1,MV2. Sets the mem voltage per gpu in mV. Not used for Navi or Big Navi gpus.
—clk_timing=V1,V2. Selects between the driver’s available mem timing sets. Not available on all gpus and drivers.
Example of a partial command line for a four gpu system where with a Rx Vega 64, 580, 5700XT and 6800 mining ethash or similar. We only specify mem voltage for the Vega and 580, and only select a driver timing value for the Big Navi:
teamredminer.exe . —clk_core_mhz=1100,1000,1275,1000 —clk_core_mv=875,850,725,675 —clk_mem_mhz=1107,2100,1820,2130 —clk_mem_mv=875,850,, —clk_timing=. 1
Варианты управления вентилятором
—fan_control(=CFG1,CFG2. ) This argument enables gpu fan control by the miner. TRM supports auto-adjusting the gpu fan speed(s) based on core, junction and/or mem temp.
We also support setting a static fan speed in percent.
Each gpu type has a fan configuration that will be used by default. We support both overriding the default configuration per gpu type as well as setting a specific config per gpu in the rig.
A fan config consists of (max) six values, separate by the ‘:’ (colon) char. The values are: core target temp, junction target temp, mem target temp, initial fan speed in percent, min fan speed in percent, max fan speed in percent. Any value can be left empty.
These are a few examples:
- ::70:50:25 Target mem temp to 70C, start fan at 50% speed, min fan speed 25%.
- 55. 20:80 Target core temp to 55C, start fan at default configuration’s speed, always keep fan between 20% and 80%.
- 55::75:80 Adjust fan so that core temp is
- . 100 Set static fan speed to 100%, never adjust based on temps.
The fan configuration used for a gpu is derived in the following precedence order:
- The —fan_control argument was passed a list of configurations and included an entry for gpu X.
- The default fan configuration for this gpu type was overridden with a —fan_default_=. parameter.
- Use the built-in default fan configuration for this gpu type.
In the list above, if the chosen configuration is missing the start value for the fan the setting from the next configuration is used.
NOTE: fan support is a beta feature and will not work better than the support the drivers provide. For example, many times the drivers under linux don’t allow forcing a fan to 100% using the sysfs pwm support.
—fan_default_polaris=CFG Set the default config used for all Polaris gpus (450/460/550/560/470/480/570/580/590).
The built-in default is 55. 50 for 55C core temp and fan starting at 50%.
Note: this setting is also reused for Tonga gpus.
—fan_default_vega=CFG Set the default config used for all Vega gpus (Vega 56/Vega 64).
The built-in default is 55::70:50 for 55C core temp, 70C mem temp and fan at 50%.
—fan_default_vega2=CFG Set the default config used for all Radeon VII gpus.
The built-in default is 70::75:80 for 70C core temp, 75C mem temp and fan at 80%.
—fan_default_navi=CFG Set the default config used for all Navi (Navi10).
The built-in default is 60::80:70 for 60C core temp, 80C mem temp and fan at 70%.
—fan_default_big_navi=CFG Set the default config used for all Big Navi (Navi21).
The built-in default is 50. 70 for 50C core temp and fan at 70%. The reason for not including mem temp is a missing sensor in the Windows ADL library.
—fan_debug Enable log printouts related to adjustments.
Параметры сторожевого таймера
—no_gpu_monitor Disables the ADL (Windows) or sysfs (Linux) GPU monitor for temperature and fan speed.
—temp_limit=TEMP Sets the core temperature at which the miner will stop GPUs that are too hot.
Default is 85C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the listis used.
—temp_resume=TEMP Sets the core temperature below which the miner will resume GPUs that were previously stopped due to the core temperature exceeding limit.
Default is 60C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_limit=TEMP Sets the mem temperature at which the miner will stop GPUs that are too hot.
Default is not enabled. Only used if the gpu provides a mem temperature sensor.
Gpu-specific values can be provided using a comma-separated list, one value per gpu.
If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_resume=TEMP Sets the mem temperature below which the miner will resume GPUs that were previously stopped due to mem temperature exceeding limit.
Default is not enabled. Only used if the gpu provides a mem temperature sensor. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—watchdog_script(=X) Configures the gpu watchdog to shut down the miner and run the specified platform and exits immediately. The default script is watchdog.bat/watchdog.sh in the current directory, but a different script can be provided as an optional argument, potentially with a absolute or relative path as well.
—watchdog_test Tests the configured watchdog script by triggering the same action as a dead gpu after ~20 secs of mining.
—watchdog_disabled Forces the watchdog to not execute. Can be used to disable the watchdog in mining os that always run with the watchdog enabled.
Ethash опции
—eth_config=CONFIG Manual ethash configuration for the miner. CONFIG must be in the form [X][M][L] .
- The [M] value selects the mode which can be ‘A’,’B’, or ‘C’.
- The B mode uses additional memory and will only work on 8+GB cards.
- The C mode uses additional memory and will only work on 16+GB cards, such as the VII, with a correctly configured system. See the ETHASH_TUNING_GUIDE.txt for more details.
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
- The [X] prefix is optional and is Navi/Big Navi only, it enables more mem operations and leads to a lower tuning [L] value. It can be beneficial whenever the auto-tuner repeatedly hits a value close to the max possible tuning value for the gpu.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —eth_config=A
- —eth_config=B750
- —eth_config=XB
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—eth_variant_mode=X This argument controls activation of the ethash changes for ETC from epoch 390 as described in ecip-1099.
The following modes are available:
pool — Default mode. Only activates if the pool sends an algo flag containing etchash.
Once this flag is seen, all pool jobs will be assumed to be etchash unless another.
algo flag containing ethash is received.
etchash — Etchash mode. Epoch >= 390 will be assumed to be etchash, lower epochs ethash. Pool algo flags are not used.
deduce — Ignore pool algo flags and only apply a heuristics based on the current system time and known heights and times for ETC and ETH. This mode should work as a generic approach when ETH reaches epoch 390 in Jan 2021. The system clock needs to be correct.
It should also handle any profit switching setups that switch freely between ethash and etchash jobs by proxying underlying pools.
auto — As long as the pool hasn’t passed an algo flag, use deduce mode. When an algo flag is seen, switch to pool mode.
ethash — Forced ethash mode. Never apply ecip-1099.
force_etc — Forced etchash mode. Always apply ecip-1099 rules. Use for ETC testnet mining.
—eth_aggr_mode Enables automatic use of the ‘B’ mode for all Polaris 8GB cards, unless they have a different config provided by the —eth_config argument. This is the same thing as manually setting all Polaris 8GB gpus in the rig to ‘B’ mode using —eth_config .
For most gpus, this adds 0.1-0.2 MH/s of hashrate.
NOTE: 20-25% of rigs becomes less stable in this mode which is the reason it isn’t the default mode. If you experience dead gpus, you should remove this argument and run the gpus in the ‘A’ mode.
—eth_stratum_mode=MODE Sets a fixed stratum mode for ethash pools.
By default the miner will attempt to automatically determine the type of stratum the pool supports and use that mode. This automatic detection can be overriden by specifying this option. The MODE can be set to one of the following options: stratum, nicehash, ethproxy.
—eth_worker Set the worker id that will be sent to pool. This only applies to pools with ethproxy stratum mode.
—eth_hash_report=X Controls hashrate reports to the configure pools. This value is applied for all pools.
- default — let the miner decide based on stratum protocol used for each pool.
- force — always send hashrate reports, even if the pool rejects them.
- on — send a first hashrate report, disable for any pool that rejects the message.
- off — never send hashrate reports.
—eth_epoch Tests a specific ethash epoch. NOTE: you still need to provide a pool as if you were mining, but no shares will be submitted. Simulated mining only.
—eth_alloc_epoch=N Allocates enough memory for the given epoch from the start. The miner will try to allocate more if it needs to later during mining. It’s recommended for rigs with one or more 4GB cards to test and set this to the max possible value to avoid reallocations at epoch switches. Optimal Linux rigs should be able to handle epoch 380, Windows rigs a little less (373-374).
—eth_dag_buf=X,Y. The miner can allocate a single or dual buffers for the DAG. For now, the default is DUAL buffers, which matches the behavior in all recent TRM releases. However, a single buffer is slightly better, leading to a small power save for all gpu types. Only recent drivers support single large allocations larger than 4GiB, typically from Adrenalin 20.9.1 and amdgpu-pro 20.x. The miner can automatically use single buffer mode when possible using this argument, as well a force single or dual buffers per gpu.
Supported values are
You can enumerate a comma-separated list for all gpus in the rig, or a single value for all gpus. A gpu that does not have a value in the comma-separated list will use the first value. Hence, to enable auto mode for all gpus, pass —eth_dag_buf=A NOTE: 4GB gpus will be forced to use dual buffers.
—eth_big_mode_adjust=X,Y. When using B- or C-modes, the miner runs better the more vram it can allocate. Unfortunately the drivers aren’t accurate reporting how much memory it’s possible to allocate, especially on Windows.
The miner will use a safe conservative number of 256MiB (Linux) and 512MiB (Windows) as an offset from the available vram size. If you want change this number, you can do so using this argument by providing.
a comma-separated list with values for one or more gpus. Values for gpus not running B/C-mode will be ignored. If a gpu doesn’t have a value in the list, the first provided value is used instead.
The allowed interval is [-64, 2048]. The higher number, the less vram is allocated on the gpu.
—eth_4g_max_alloc=X,Y. This argument allows mining on 4GB gpus after they no longer can store the full DAG in vram.
You pass either the max epoch to allocate memory for, or the raw nr of MB to allocate. You can provide a single value that applies to all 4GB gpus in the rig, or use a comma-separated list for specifying different values per gpu. Values for non-4GB gpus are ignored.
—eth_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (
—eth_stagger Enables staggering of gpus when building a new DAG. This is more lean on PSUs that don’t like going from 0-100% load on all gpus at the same time.
—eth_no_stagger Disables –eth_stagger. Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_ramp_up Adds ramping up the intensity on all gpus after a DAG build, gpu disable/enable or network outage. Can help rigs with crashes right between the DAG build and starting mining.
—eth_no_ramp_up Disables —eth_ramp_up . Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_direct_abort Uses a different mechanism to abort ongoing gpu jobs. Recommended for Vegas in ROCm environments to minimize stale shares. Will apply to Vega and Polaris gpus in the rig only.
—eth_dag_alloc_patch Some motherboards with outdated bios can see hw errs typically on the first or last gpu in the system.
Use this argument to force a patched dag allocation strategy that most often solves the issue.
Upgrading your bios often solves the issue as well.
—eth_hashwatch(=M,M) Defines a min/max watchdog hashrate in MH/s expected when gpus are hashing. If a GPU falls outside of this range for too long it will be considered faulty and the watchdog will be triggered. The default min/max values are 2 MH/s and 150 MH/s.
To activate with default values, use —eth_hashwatch . To set your own values, use e.g. —eth_hashwatch=1.25,60 . The same range is used for all gpus in the rig. A negative value for one side disables it, e.g. use —eth_hashwatch=-1,1000 to handle gpu resets that result in huge fake hashrates but no minimum check.
—eth_dag_cache(=EPOCH) Enables saving eth DAGs from jobs with different epochs to prevent having to rebuild them in the future if jobs with the old epochs are received again. At most one DAG will be saved if GPU memory space allows. This is useful for switching pools such as eth+zil mining.
If you want to prebuild a certain epoch immediately at startup, add the optional value. Eth+zil switching miners should use —eth_dag_cache=0 . Only ethash (and not etchash) epochs can be prebuilt at this time.
—eth_dag_cache_resv=MEM Sets the amount of GPU memory the miner will attempt to leave unused when running with DAG caching enabled (see –eth_dag_cache). The argument MEM is the amount of memory to leave unused in mebibytes. The default value is 256.
—eth_dag_cache_verify Enable dag cache read and verification after a finished dag build. This will detect situations where the dag cache had bit errors and the resulting dag is partially broken.
We have seen this happen increasingly on Vegas as the dag has grown bigger. When detected, a new buffer will be allocated for the dag cache and the dag build restarted.
—eth_no_4gb_kernels Disable the ethash 4GB kernels and always use the regular kernels that assume the DAG will always fit in available vram on all gpus.
This is useful when mining ETC or ethash coins at lower epochs than ETH since the regular kernels have a better performance profile.
—eth_micro_delay=VAL Navi gpus only: adds a delay (measured in microseconds) when reenqueueing work on the gpu(s).
Weaker PSUs driving many gpus can sometimes not handle the “slew rate” when multiple gpus happen to reenqueue work at exactly the same time. Setting this to e.g. 32 will smoothen out the transition from no load to 100% load enough to lower the slew rate on such rigs.
The typical indication of this issue is hard hangs where the rig becomes unresponsive requiring a power cycle to reboot, but it can also be regular gpu crashes. Valid values are 1-128. Not using this argument means no delay, value zero.
Progpow опции (kawpow, firopow)
—prog_config=CONFIG Manual progpow configuration for the miner. CONFIG must be in the form [M][L].
- The [M] value selects the mode which can be either ‘A’ or ‘B’.
- The ‘B’ mode typically results in better performance but is only available for
- Vega on linux and Navi (linux or windows).
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —prog_config=A
- —prog_config=B750
CONFIG can also be a comma separated list of config values where each is applied to each GPU. For example: —prog_config=A,B750,,A288
Any gpu that does not have a specific config in the list will use the first.
—prog_height=VALUE Sets a fixed block height for progpow algorithms for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
—prog_strict Forces miner to always generate strictly accurate kernels. By default the miner will generate relaxed kernels that use less computation power but can result in occasional invalid shares.
—prog_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (
—prog_stagger See `–eth_stagger.
—prog_ramp_up See `–eth_ramp_up.
—prog_no_stagger See `–eth_no_stagger.
—prog_no_ramp_up See `–eth_no_ramp_up.
—prog_micro_tune=X,Y. This option enables a small retuning session for every new random code block. This is important for Polaris gpus to run at their max speed. For Vegas and Navis it usually does not improve performance. The default AUTO mode enables it for all Polaris gpus but disables it otherwise.
The only reason to disable it would be for stability purposes. The argument value is a comma-separated list of values, one per gpu. If a gpu is missing a value, the value for the first gpu is used. Please note that setting a manual prog_config will effectively disable the micro-tuner as well. Available values are:
-
- turn OFF progpow micro-tuning for this gpu.
-
- turn ON progpow micro-tuning for this gpu.
-
- let the miner decide if micro-tuning should be enabled (AUTO).
Cryptonight опции
—rig_id Set the rig identifier that will be sent to the pool. This is only used for cryptonight pools.
—cn_config=CONFIG Manual cryptonight configuration for the miner. CONFIG must be in the form [P][I0][M][I1][:xyz], where [P] is an optional prefix and [:xyz] is an optional suffix.
For [P], only the value of ‘L’ is supported for low-end GPUs like Lexa/Baffin. [I0] and [I1] are the thread intensity values normally ranging from 1 to 16, but larger values are possible for 16GB gpus.
[M] is the mode which can be either ‘.’, -‘, ‘+’ or ‘*’. Mode ‘.’ means that the miner should choose or scan for the best mode.
Mode ‘*’ both a good default more and should be used if you mine on a Vega 56/64 with modded mem timings.
The exceptions to this rule are small pad variants (cnv8_trtl and cnv8_upx2), they should still use ‘+’. For Polaris gpus, only the ‘-‘ and ‘+’ modes are available.
NOTE: in TRM 0.5.0 auto-tuning functionality was added, making manual configuration of the CN config modes unnecessary except for rare corner cases. For more info, see the tuning docs and how-to documents bundled with the release.
- —cn_config=15*15:AAA
- —cn_config=14-14
- —cn_config=L4+3
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—no_cpu_check Disables cpu verification of found shares before they are submitted to the pool.
Note: only CN algos currently supports cpu verification.
—no_lean Disables the CN lean mode where ramp up threads slowly on start or restart after network issues or gpu temp throttling.
—no_interleave=DEVS Lists gpu devices where CN thread interleave logic should be not be used.
The argument is a comma-separated list of devices like for the -d option.
Use this argument if some device(s) get a worse hashrate together with a lot of interleave adjust log messages.
—alloc_patch=DEVS Lists gpu devices that loses hashrate between TRM v0.4.5 and later versions. With this argument a simpler mem allocation strategy is used, and the old (higher) hashrate should be restored. Auto-tuning mode can still be used.
—auto_tune=MODE Enable the auto-tune mode upon startup. Only available for CN variants. MODE must be either NONE, QUICK or SCAN. The QUICK mode checks a few known good configurations and completes within 1 min. The SCAN mode will check all possible combos and will run for 20-30 mins. Setting MODE to NONE disable the auto-tune feature. The default mode is QUICK.
—auto_tune_runs(=N) Executes multiple runs for the auto tune, each time decreasing the unit of pads used -1 in one of the threads (15+15 -> 15+14 -> 14+14 -> 14+13 -> …). You can specify the explicit nr of runs or let the miner choose a default value per gpu type (typically 3-4).
—auto_tune_exit If present, the miner will exit after completing the auto-tuning process. This is helpful when you want to scan for optimal settings and then use the resulting command line arg printed by the miner.
—allow_large_alloc If present, and when the driver indicates there is enough GPU vram available, the miner will be more aggressive with the initial memory allocation. In practice, this option means that Vega GPUs under Linux will start the auto-tuning process at 1615 rather than 1614 or 15*15.
MTP опции
—allow_all_devices Some algos can’t be mined on e.g. 4GB gpus. Those gpus will be disabled automatically by the miner. This argument overrides this logic and allows mining on all specified or detected devices.
X16* опции
—hash_order=VALUE Sets a fixed hash order for algorithms like x16r for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
The standard benchmark hash order for x16r is —hash_order=0123456789abcdef .
Nimiq опции
—nimiq_worker=VALUE Sets the worker/device name for nimiq to pass to the pool(s).
—nimiq_no_proxy Disables the automatic Nimiq proxy executed as a separate process. This means that the host and port passed to the miner must be pointing to a proxy.
—nimiq_proxy=VALUE Overrides the default path to the Nimiq proxy. The default is trm_nimiq_proxy-win.exe. and trm_nimiq_proxy-linux in the current miner director.
—nimiq_port=VALUE Overrides the default local port (4444) used for the Nimiq proxy. This can be used if your system is already using port 4444 for some other tcp/ip service.
Verthash опции
—verthash_file=FILE Sets the filename to be used to load/store the verthash data file. If this option is specified when the verthash algo is used, the miner will attempt to load the verthash data from the file. If the file does not exist, the miner will generate the verthash data and then save it in the file for future use.
If this option is not specified the miner will generate the verthash data in system memory on every start.
—verthash_max_uploads=N Some motherboards have issues with all gpus in the rig uploading the verthash table at the same time. This argument limits the number of concurrent gpus that are uploading the table at the same time at startup. Allowed values are 1-32. The default value is 4.
Autolykos2 опции
—autolykos_mem_adjust=N Sets the amount of memory in MiB that the miner should leave unused when allocating GPU buffers for autolykos. The default value is 384 on linux and 512 on windows.
For GPUs with displays attached, the default is increased by 512. If dual mining with ZIL, the default value is increased by 1024. The option can also be provided with a comma separated list of values where each value is applied to each GPU. If an empty value is specified in the list, the default will be used for that GPU. If a value is not specified for a GPU it will use the first value in the list.
—autolykos_slowdown=N Adds a slowdown of the pad build process. Valid values are 0-100. The default is 0, no slowdown.
—autolykos_ignore_diff Ignores the difficulty sent by the pool and only uses the 256-bit target provided in jobs.
Some pools don’t follow the ERGO reference miner pool implementation, in which case this argument might help. NOTE: this will be applied to all pools.
ZIL dual mining опции
—zil_start or —zil Starts the ZIL dual mining config. Between this and the —zil_end marker , all arguments are applied to the ZIL mining rather than the primary algo. It’s expected that the primary algo has been set up in earlier arguments. The intention is that you can add a —zil . —zil_end configuration to any working TRM configuration algo and things will work out of the box.
This argument automatically sets a range of default settings you want to use for ZIL:
- Cached copy of the ZIL epoch 0 DAG.
- Adjustment of memory allocated for the primary algo to fit the ZIL DAG.
- Choose ethash A-mode for the ZIL mining.
- Use the standard faster kernels for 4GB gpus since the DAG is max 1GB.
The minimal working setup is to only provide a ZIL pool that is ok with the miner ignoring the primary coin jobs and only mines during the ZIL windows. This is an example for ezil.me:
For more info, read the ZIL dual mining guide packaged with the TRM release.
—zil_end Marks that we’re done with the ZIL mining config and all following arguments are for the primary algo. This argument isn’t strictly necessary, but should be included for mining distros since the user has no guarantee what arguments will be added automatically at the end of the command line by the distro.
—stats_mode=single/dual When adding ZIL dual mining, the stats output will by default be duplicated to add info for the ZIL mining. Some contexts might get confused by this if they are parsing the TRM outut or log files. To switch to the default output, add —stats_mode=single .
Download now
Latest version is 0.10.14
File: *teamredminer.exe,
SHA256: 37516f09d12166978577e24efa4779cc13f1f2b645d15a9527fcba8b9940c89d
Based on 3,200+ reviews
Браузер не поддерживается
Вы используете браузер, который Facebook не поддерживает. Чтобы все работало, мы перенаправили вас в упрощенную версию.
Разрешить использование файлов cookie от Facebook в этом браузере?
Мы используем файлы cookie и подобные технологии, чтобы показывать и улучшать контент в Продукты Meta, обеспечивать безопасный пользовательский опыт с помощью информации, полученной из файлов cookie от Facebook и других источников, а также чтобы предоставлять и улучшать Продукты Meta для зарегистрированных пользователей.
- Основные файлы cookie. Эти файлы cookie необходимы для использования Продуктов Meta и корректной работы наших сайтов.
- Файлы cookie от других компаний. Мы используем эти файлы cookie, чтобы показывать вам рекламу вне Продуктов Meta и предоставлять такие функции, как карты и видео, в Продуктах Meta. Эти файлы cookie не обязательны.
Вы можете контролировать, какие необязательные файлы cookie мы используем. Подробнее о том, что такое файлы cookie и как мы их используем, а также о том, как посмотреть и изменить настройки, вы можете узнать в нашей Политика в отношении файлов cookie.
Информация о файлах cookie
Что такое файлы cookie?
Файлы cookie — это небольшие текстовые файлы, которые используются для хранения и получения идентификаторов в браузере. Мы используем файлы cookie и аналогичные технологии, чтобы предоставлять вам Продукты Meta и анализировать полученную информацию о пользователях (например, сведения об их действиях на других сайтах и в других приложениях).
Если у вас нет аккаунта, мы не используем файлы cookie, чтобы персонализировать для вас рекламу. Информация о ваших действиях, которую мы получаем, будет использоваться только для обеспечения безопасности и целостности наших Продуктов.
Больше информации о файлах cookie и аналогичных используемых технологиях — в нашей Политика в отношении файлов cookie.
Почему мы используем файлы cookie?
Файлы cookie помогают нам предоставлять, защищать и улучшать Продукты Meta, например с помощью персонализации контента, подбора и оценки рекламы, а также повышения безопасности их использования.
Хотя файлы cookie, которые мы используем, могут время от времени меняться по мере улучшения и обновления Продуктов Meta, мы используем их для следующих целей:
- Выполнять аутентификацию, чтобы пользователям не приходилось входить каждый раз повторно
- Чтобы обеспечивать безопасность и целостность сайтов и продуктов
- Показ рекламы, предоставление рекомендаций, статистической информации и количественных оценок (если показ рекламы разрешен)
- Чтобы предоставлять функции и услуги на сайтах
- Чтобы оценивать производительность наших Продуктов
- Чтобы обеспечивать возможность анализа данных и проведения исследований
- На сторонних сайтах и в сторонних приложениях — чтобы помочь компаниям, использующим платформы Meta, делиться с нами информацией о действиях в их приложениях и на их сайтах.
Узнайте подробнее, что такое файлы cookie и как мы их используем, в нашей Политика в отношении файлов cookie.
Что такое Продукты Meta?
Продукты Meta включают в себя приложения Facebook, Instagram и Messenger, а также любые другие функции, приложения, технологии, программное обеспечение или услуги, предлагаемые Meta в соответствии с нашей Политикой конфиденциальности.
Подробнее о Продукты Meta в нашей Политике конфиденциальности.
Ваши настройки файлов cookie
Вы можете контролировать, какие необязательные файлы cookie мы будем использовать:
- Мы можем использовать наши файлы cookie в других приложениях и на других сайтах, принадлежащих компаниям, которые используют возможности платформ Meta (например, кнопку «Нравится» и пиксель Meta), для персонализации показываемой вам рекламы (если ее показ разрешен).
- Мы используем файлы cookie от других компаний, чтобы показывать вам рекламу вне Продуктов Meta и предоставлять такие функции, как карты и видео, в Продуктах Meta.
Вы в любое время можете проверить или изменить свои параметры в настройках файлов cookie.
Файлы cookie других компаний
Мы используем файлы cookie от другие компании, чтобы показывать вам рекламу вне наших Продуктов и предоставлять такие функции, как карты, платежные сервисы и видео.
Как мы используем эти файлы cookie
Мы используем файлы cookie от других компаний в наших Продуктах:
- Чтобы рекламировать наши Продукты и функции в приложениях и на сайтах других компаний.
- Для предоставления таких функций наших Продуктов Meta, как карты, платежные услуги и видео.
- Для аналитики.
Если вы разрешите использовать эти файлы cookie
- Это не повлияет на работу используемых вами функций в Продуктах Meta.
- Мы сможем лучше персонализировать для вас рекламу вне Продуктов Meta и измерять ее результативность.
- Другие компании будут получать информацию о вас с помощью своих файлов cookie.
Если вы не разрешите использовать эти файлы cookie
- Некоторые функции в наших продуктах могут не работать.
- Мы не будем использовать файлы cookie других компаний для персонализации рекламы вне Продуктов Meta или измерения ее результативности.
Другие способы управления вашими данными
Управляйте показом рекламы в Центре аккаунтов
Вы можете управлять показом рекламы с помощью следующих настроек.
Рекламные предпочтения
В настройках рекламных предпочтений вы можете разрешить или запретить показ рекламы, а также определить, какую информацию мы можем использовать для показа этой рекламы.
Настройки рекламы
В целях более точного подбора рекламы, которую мы вам показываем, мы используем данные о ваших действиях вне Продуктов компаний Meta, полученные от рекламодателей и других партнеров (в том числе сайтов и приложений). В настройках рекламы вы можете разрешить или запретить использование этих данных для показа вам рекламы.
Подробнее об онлайн-рекламе
Вы можете отказаться от онлайн-рекламы на основе интересов на сайте Альянса цифровой рекламы в США, Альянса цифровой рекламы Канады, если вы находитесь в Канаде, и Европейского альянса интерактивной цифровой рекламы — в ЕС. Таким способом можно заблокировать показ рекламы, которую для вас подбирает Meta и другие компании, состоящие в указанных организациях. Настройки для отказа от персонализированной рекламы также доступны на мобильных устройствах с Android, iOS 13 или более ранней версией iOS. Важно! Средства блокировки рекламы или ограничения использования файлов cookie могут препятствовать действию описанных здесь инструментов управления.
Большинство рекламодателей, с которыми мы сотрудничаем, используют файлы cookie и подобные технологии для обеспечения корректной работы своих сервисов. Чтобы узнать подробнее, как рекламодатели обычно используют файлы cookie и какой выбор в связи с этим предлагается пользователям, см. следующие ресурсы:
- Альянс цифровой рекламы
- Альянс цифровой рекламы Канады
- Европейский альянс интерактивной цифровой рекламы
Управление использованием файлов cookie c помощью настроек браузера
В браузере или на устройстве, которые вы используете, могут быть настройки, позволяющие задать параметры использования файлов cookie и удалить их. Эти настройки различаются в разных браузерах, и производители могут в любой момент изменить набор предлагаемых параметров и то, как они работают. Начиная с 5 октября 2020 г. по ссылкам ниже можно найти дополнительную информацию о настройках, доступных в популярных браузерах. Если в браузере заблокировано использование файлов cookie, некоторые функции Продуктов Meta могут работать некорректно. Обратите внимание, что настройки браузеров отличаются от настроек Facebook.
- Google Chrome
- Internet Explorer
- Firefox
- Safari
- Safari для мобильных устройств
- Opera